Talweg
· Talweg Team · Architecture · 4 min read
The Future of the Modern Data Stack: Where Real-Time AI Fits In
A look at how tools like Apache Flink and declarative stream processing are reshaping modern data architectures, bringing real-time AI into the mainstream.
Introduction
The “Modern Data Stack” (MDS) has radically transformed how organizations store, transform, and analyze data. Built around cloud data warehouses, modular ELT (Extract, Load, Transform) pipelines, and powerful BI tools, the MDS successfully democratized data access. However, as the demand for immediate insights and automated actions accelerates, the traditional MDS architecture—fundamentally rooted in batch processing—is hitting its limits.
Enter Real-Time AI and Stream Processing.
As we look toward the future, the modern data architecture is evolving. Tools like Apache Flink and declarative frameworks like FlinkFlow are no longer just edge-case technologies for niche engineering teams; they are becoming central pillars of the next-generation data stack.
The Batch Processing Bottleneck
The traditional MDS is inherently asynchronous. Data is extracted from source systems, loaded into a warehouse, and periodically transformed (often using tools like dbt) before it reaches analysts or dashboards.
This model is excellent for historical reporting, deep-dive analytics, and training complex machine learning models offline. But what happens when you need to detect credit card fraud the moment a transaction occurs? What if you want to personalize an e-commerce recommendation based on a user’s clickstream data from the last three seconds?
Batch architectures cannot support these use cases efficiently. The latency introduced by polling, loading, and querying large datasets makes real-time action impossible. Furthermore, attempting to run batch processes at sub-minute intervals (often called “micro-batching”) quickly leads to skyrocketing compute costs and fragile pipelines.
The Shift to Streaming Architectures
To bridge the gap between event occurrence and business action, organizations are turning to stream processing. Apache Flink has emerged as the de-facto standard for stateful, high-throughput, low-latency data streaming.
Instead of waiting for data to land in a database, Flink processes data in motion. It allows you to:
- Continuously compute aggregations over sliding time windows.
- Instantly join fast-moving event streams with slow-moving reference data (like user profiles).
- Maintain complex state across millions of concurrent events.
By moving the processing logic upstream, closer to the data sources (like Kafka or Kinesis), systems can react to events in milliseconds.
Where Real-Time AI Changes the Game
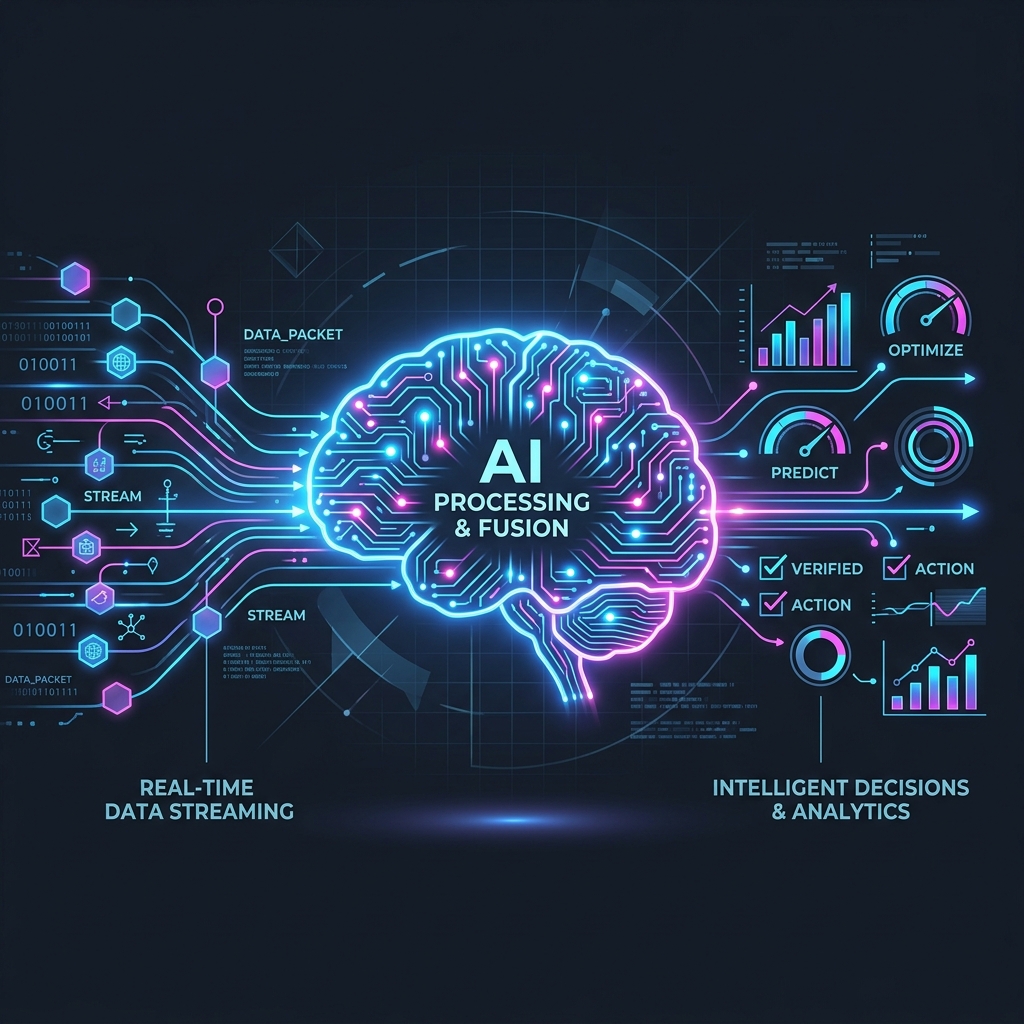
Real-time streaming is powerful, but when combined with Artificial Intelligence, it becomes transformative. Real-time AI involves executing machine learning models directly against streaming data.
Key Use Cases for Real-Time AI:
- Dynamic Pricing: Adjusting prices on the fly based on current demand, inventory levels, and competitor pricing, rather than relying on yesterday’s sales data.
- Predictive Maintenance: Analyzing sensor telemetry from manufacturing equipment to predict and prevent failures before they happen, rather than running batch reports on equipment downtime.
- Instant Fraud Mitigation: Scoring transactions against ML models in milliseconds to decline fraudulent purchases instantly.
- Hyper-Personalization: Serving customized content or product recommendations based on a user’s immediate context and behavior in the current session.
The Role of Declarative Stream Processing
Historically, integrating stream processing and real-time AI into the data stack was incredibly difficult. It required specialized distributed systems engineers writing complex Java or Scala code. It was an expensive and time-consuming endeavor reserved for tech giants.
This is where the paradigm is shifting. The future of the data stack is declarative.
Frameworks like FlinkFlow are bringing the simplicity of the MDS to the streaming world. By allowing data teams to define complex stream processing and AI pipelines using declarative syntax (like SQL or simple configuration files), the barrier to entry plummets.
Why Declarative Changes Everything:
- Accessibility: Data analysts and scientists who already know SQL can now build real-time pipelines without needing to learn Java or understand the intricacies of Flink’s distributed state management.
- Speed to Market: Prototyping and deploying real-time AI use cases takes hours or days instead of months.
- Maintainability: Declarative code is easier to read, version control, and maintain, reducing technical debt.
Integrating Streaming into the Modern Data Stack
The future isn’t about replacing the batch-oriented MDS; it’s about complementing it. We are moving toward a unified architecture where stream processing and batch processing work in harmony.
- The Streaming Layer: Flink handles real-time ingestion, continuous transformations, stateful aggregations, and real-time AI inference. It drives operational dashboards, automated alerts, and real-time user experiences.
- The Unified Storage & Serving Layer (Apache Fluss): Traditionally, this required separate databases (like Pinot or ClickHouse). Now, tools like Apache Fluss provide a streaming storage system that acts as a real-time table. It supports high-throughput appending for streams while simultaneously serving low-latency point lookups, effectively bridging the gap between streaming and storage.
- The Batch/Lakehouse Layer: For deep historical analytics and training complex offline models, Flink sinks the processed data into Lakehouses (Iceberg, Hudi) or traditional data warehouses. With Fluss acting as the real-time counterpart to these Lakehouses, the architecture becomes dramatically simpler.
Conclusion
The Modern Data Stack solved the problem of scalable analytics. The next frontier is operationalizing that data in real-time. By embracing stream processing technologies like Apache Flink and leveraging declarative frameworks like FlinkFlow, organizations can seamlessly weave Real-Time AI into their architectures.
The future belongs to the businesses that can not only understand what happened yesterday, but can act intelligently on what is happening right now.